SaaS Status Monitoring Tools: StatusGator vs Better Stack
The operational reliability of SaaS platforms is an ever-present concern for businesses, especially those with critical dependencies and globally distributed teams. StatusGator and Better Stack have emerged as leading SaaS status monitoring tools, but their approaches, depth of coverage, and operational maturity vary dramatically. To make an informed decision, IT, DevOps, and business continuity teams must assess each platform across key technical, operational, and economic dimensions—which is what this head-to-head analysis provides.
Separate Vendor Status Aggregation From Independent Service Checks
One of the foundational differences between SaaS status monitoring tools is whether they aggregate publicly reported vendor statuses or perform their own synthetic and independent checks. This architectural distinction creates meaningful implications for coverage, accuracy, and trust in incident reporting.
- StatusGator: Operates as a powerful aggregation platform, tracking and normalizing public status pages from hundreds of cloud, SaaS, and infrastructure vendors. StatusGator excels at vendor breadth, providing a consolidated dashboard for third-party SaaS status with minimal setup. It does not, however, run its own active synthetic monitoring for these services by default.
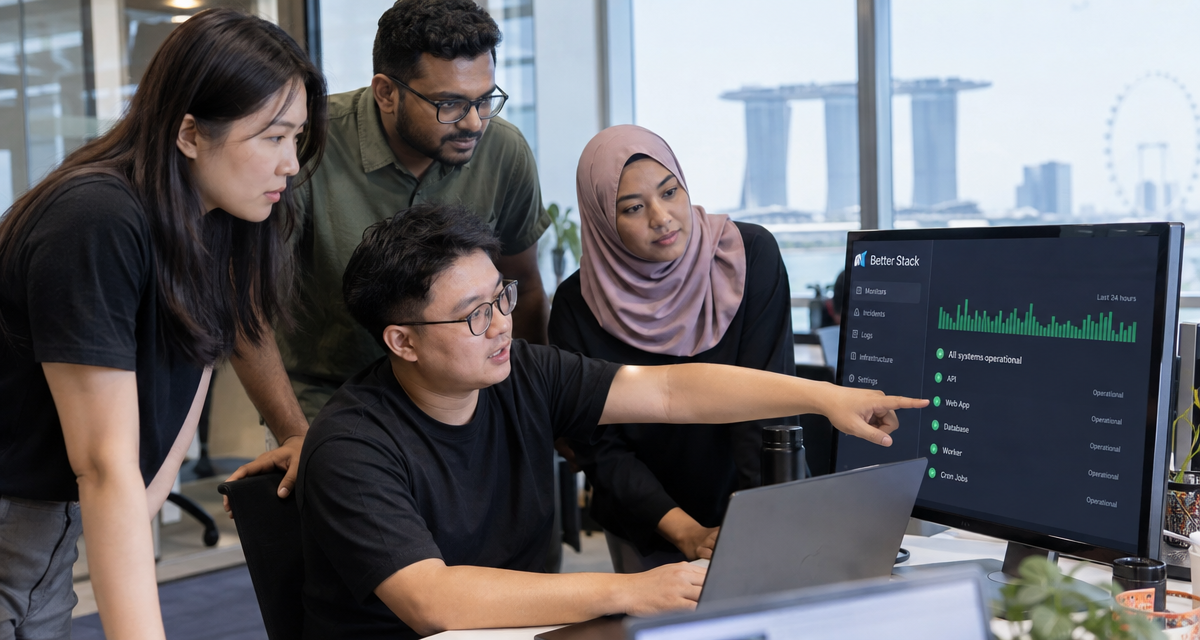
- Better Stack: Focuses on active, independent health checks using synthetic testing, custom probes, and native integrations. Rather than rely solely on vendor-supplied status updates—which are often delayed or sanitized—Better Stack can test endpoints, APIs, or user journeys directly from multiple regions, supplementing vendor feeds as required.
The real-world friction comes from onboarding complexity versus transparency. StatusGator can be deployed instantly, covering hundreds of upstream SaaS vendors out of the box. However, operational teams cede some visibility and must trust vendors to surface outages accurately and promptly. Better Stack requires more upfront configuration—especially for custom APIs or internally hosted services—but gives organizations the autonomy to define what “up” really means in business terms.
- Operational Risk: With pure aggregation tools, you face the risk of false green lights during partial vendor outages not reported on public status pages. If regulatory or customer SLAs demand defensible RTO/RPO, independent checks become non-negotiable.
- Integration Overheads: StatusGator is almost zero-effort for aggregation. Better Stack’s independent checks introduce setup overhead but dramatically increase incident detectability for core business services.
Smart teams often use both architectures in tandem: aggregate third-party SaaS statuses to catch upstream vendor events, and supplement with independent checks for business-critical user journeys.
Define the Services and User Journeys You Need to Monitor
The flexibility with which you can define, structure, and evolve monitoring targets is a critical differentiator between these two platforms. Modern SaaS status monitoring tools must go beyond static uptime checks, covering real-world business transactions and complex cloud dependencies.
- StatusGator: At its core, StatusGator operates on list-based monitoring—you select which vendor services to track, and it reports aggregated status changes. It is well-suited for keeping tabs on critical tools like AWS, Microsoft 365, Zoom, or payment gateways, but does not natively model bespoke application flows or simulate user journeys. Service tracking can be grouped by type, team, or function, but lacks advanced journey orchestration.
- Better Stack: Provides granular flexibility to define HTTP, DNS, SSL, TCP, or custom synthetic checks. Teams can model end-to-end user flows, multi-step transactions, or internal API tests, chaining steps and assertions as needed. For example, you could monitor the latency and content of a checkout workflow across regional endpoints, directly from Singapore or any number of global nodes.
Where this matters most is in service mapping and compliance:
- Organizations with clear, vendor-centric dependencies (think 200 SaaS products in a large enterprise), StatusGator offers “set and forget” simplicity and native aggregation.
- For technical teams responsible for in-house apps, customer-facing APIs, or regulated industries (finance, healthcare), Better Stack’s scripting and custom flows enable rigorous, scenario-based testing that’s auditable and business aligned.
A hidden trade-off: StatusGator’s scope is fixed by what vendors publicly disclose. Better Stack, while more powerful for custom checks, requires teams to explicitly define and update monitoring logic as services and products evolve.
Compare Provider Incident Visibility and Synthetic Checks
The method and granularity of outage detection is where most status monitoring strategies succeed or fail. Here’s how the two platforms differ:
- StatusGator: Offers incident visibility strictly tied to the upstream vendor’s public feed. When AWS, Salesforce, or Okta update their status, StatusGator relays this immediately. With filtering options, you can control how much noise is surfaced and automate escalation based on incident severity. The chief limitation: lack of proactive detection if a vendor is slow to acknowledge issues.
- Better Stack: Delivers incident visibility via a combination of real-time synthetic checks and vendor status feeds (if optionally enabled). Synthetic probes run from multiple edge locations, allowing the platform to catch partial, regional, or network-induced degradations before a vendor confirms a problem. Incident context includes response codes, error payloads, and timing metrics, supporting root cause isolation.
Key operational distinctions:
- Speed: Better Stack can typically detect outages 5–30 minutes (or more) ahead of vendor status updates. This window is critical for customer-facing SLAs and executive communication during service interruptions.
- Depth: StatusGator provides a normalized, vendor-centric incident log for compliance and oversight, not for API-level troubleshooting.
The primary friction is data reliability vs. control: Some regulated businesses may require evidence that an incident was independently verified. Teams relying solely on vendor feeds (via StatusGator or similar) can face challenges during root cause analysis or SLA disputes.
Comparison Table: StatusGator vs Better Stack Feature Matrix
| Feature | StatusGator | Better Stack | Best For |
|---|---|---|---|
| Vendor Status Aggregation | Yes, extensive directory (hundreds of public services) |
Supports, but not core focus | Large SaaS portfolios |
| Independent Synthetic Checks | No (vendor feeds only) |
Yes (custom probes & scripts) |
Custom/user journey checks |
| Customizable Workflows | Basic grouping only | Advanced, multi-step flows | Complex app monitoring |
| Integration/API Support | Webhooks, Slack, Teams APIs | Wide: Rest API, PagerDuty, SIEM | DevOps/automation teams |
| Incident Root Cause | Vendor narrative | Custom logs, probes output | Troubleshooting, audit |
| Setup Complexity | Minimal (<10 min) | Moderate–advanced (case-by-case) | Speed vs. control trade-off |
| Pricing (as of Q2 2024) | Starts at $29/mo | Free tier, Paid from $25/mo | SMB, scale-up/enterprise |
Assess Alert Routing and On-Call Workflows
Effective alert routing is essential in reducing mean time to resolution (MTTR) and avoiding alert fatigue. SaaS status monitoring tools vary in their approach to notifications, targeting, and integration into incident management tools.
- StatusGator: Offers routing via native notifications (email, SMS), integrations with Slack, Microsoft Teams, and webhooks. Alert rules can be configured by service, status change, and team, but complexity is capped by the underlying data model (vendor event only). There is no deep native integration into enterprise on-call tooling or scheduling logic.
- Better Stack: Features advanced on-call scheduling, incident escalation policies, and deep integrations with platforms like PagerDuty, Opsgenie, VictorOps, and ServiceNow. Alerts can be routed by incident severity, impacted component, region, or business hours. Custom workflows can trigger notifications conditionally—minimizing noise and automating escalation for unresolved incidents.
In Singapore-based operations or similar APAC timezones, coverage outside regular business hours is critical. Better Stack is designed to handle follow-the-sun models, letting teams specify hand-off logic, split notifications by geography, and ensure 24×7 coverage across distributed teams.
The main friction with StatusGator is its simplicity—this is a virtue for some, but a limitation for enterprises with multiple on-call shifts or tightly audited escalation paths. Better Stack’s flexibility is a double-edged sword: it enables best-in-class workflows but requires configuration investment and periodic maintenance as team structures evolve.
Configure Singapore Business-Hour and After-Hour Escalations
For SaaS-dependent companies in Singapore or across APAC, the ability to localize escalations and align notifications to regional business hours is vital—avoiding both missed overnight alerts and unnecessary “wake the team” events.
- StatusGator: Lacks intrinsic business-hour scheduling or timezone-aware escalations. Users can filter which vendors and services send alerts, but hand-off logic (e.g., between Singapore and London or US teams) must be handled externally, likely through custom scripting or downstream incident tooling. This can create gaps where ownership is unclear or coverage lapses during holidays.
- Better Stack: Has native support for configuring on-call schedules aligned to any timezone, including Singapore. Teams can define primary, secondary, and backup escalation paths. Complex hand-off patterns (e.g., business-hours primary in Singapore, after-hours fallback to Sydney or global operations) are managed via drag-and-drop schedules, removing manual setup and potential errors. Combined with API and webhook automation, this enables reliable 24×7 follow-the-sun coverage even for multi-national businesses.
A technical caveat: For both platforms, accurate scheduling presupposes that user accounts, group rosters, and escalation logic are kept up to date—otherwise, alerts may be misrouted. Better Stack’s auditability and logging help here, but process discipline is still required.
Evaluate Incident Communication Options
Incident communication is vital for both internal coordination and external messaging, especially during high-severity outages affecting customers, partners, or sensitive stakeholders.
- StatusGator: Provides a customizable internal dashboard and basic integrations for Slack, Teams, and email, but is not tailored for external stakeholder management. No built-in customer status pages or incident comms portals—customers must implement their own or use a third-party product if proactive communication is needed. This works well for teams needing a consumption layer for aggregated SaaS vendor status only.
- Better Stack: Includes sophisticated status page functionality, allowing organizations to publish real-time incident updates, root cause statements, incident history, and notifications to both internal and external audiences. Status pages can be white-labeled, branded, and segmented by customer cohort or region. APIs allow integration with customer comms tools, SMS/email triggers, and embedded incident widgets for websites or apps.
In regulated, SaaS-first industries where customer trust and transparency matter, Better Stack’s built-in comms portals can accelerate compliance and reduce manual overhead. However, they require maintenance and periodic curation to remain effective.
Test False Alarms and Missed Failures
A challenge for every monitoring platform is balancing sensitivity (catching every real outage) and specificity (avoiding noisy false alarms). False positives erode trust, while missed failures create major reputational and financial risk.
- StatusGator: Relies on vendor-reported status. This generally minimizes false alarms (as incidents are “blessed” by the provider), but risks missed outages if the vendor does not update their feed promptly or deliberately censors minor regional or intermittent failures. In practice, organizations relying solely on status aggregation report missing 10–40% of service degradations, especially those localized or transient in nature.
- Better Stack: Synthetic checks are tunable. Users can set thresholds (e.g., 3/5 failed checks globally) before escalating, reducing false positives caused by transient blips or network hiccups. However, badly calibrated checks can generate noise, and maintenance is needed to ensure alert logic keeps pace with evolving infrastructure. Periodic review of false/true positive rates is essential to maximize value.
The key trade-off: aggregation tools reduce noise but increase the risk of missing critical, unacknowledged vendor incidents; active checks maximize early detection but at the cost of engineering overhead and some risk of alert fatigue.
Compare Subscription and Maintenance Costs
Ongoing cost and resource investment is a pivotal consideration—especially as footprints, regulatory complexity, or global scale increase.
- StatusGator: Transparent SaaS model. As of mid-2024, entry pricing starts around $29/month for up to 100 tracked services. Higher tiers (business and enterprise) offer increased service and integration limits, with custom quotes for requirements over 500 services or advanced reporting needs. Maintenance overhead is negligible for basic aggregation—once setup, ongoing calibration is rarely needed unless business scope changes. The downside: limited extensibility or customization at higher tiers, so heavy enterprises may outgrow it.
- Better Stack: Has a functionally robust free tier for small teams or development use. Paid tiers start at $25/month for advanced checks, on-call integrations, and external status pages, scaling up by number of probes, API checks, and generous user limits. As checks become more granular and workflows more customized, internal engineering maintenance rises: scripts, probes, synthetic flows, and notifications must periodically be reviewed, tested, and updated with product or architecture changes.
In short, StatusGator is a low-TCO, high-speed SaaS status aggregation layer for teams with static requirements. Better Stack is a more configurable platform with true enterprise extensibility, where operational cost is dictated by organizational complexity rather than basic seat or service count.
Choose Complementary Monitoring Where Needed
In practice, mature organizations do not view StatusGator and Better Stack as binary alternatives but as complementary building blocks in a multilayered monitoring strategy.
- Large enterprises often use StatusGator to surface vendor-led outage reporting “for free”—mapping dependencies across SaaS apps and infrastructure providers, providing a compliance log for regulators and auditors.
- Better Stack is layered on for business-critical app endpoints, custom APIs, customer journey flows, or anywhere vendor feeds offer insufficient granularity or speed.
Some companies also integrate both into centralized SIEM or incident workflow platforms (ServiceNow, PagerDuty, Splunk), using aggregation for “outside in” visibility and active checks for “inside out” validation. This approach hedges against both vendor silence and false positives while optimizing mean time to detect and respond.
Emerging best practices include periodic tabletop exercises to test cross-platform alerting, regular check tuning for evolving business journeys, and governance processes to rationalize tool sprawl. Automation (both platform native and through open APIs) is increasingly leveraged to connect SaaS status insights directly to ticketing, comms, and runbook execution.
Summary Table: StatusGator vs Better Stack at a Glance
| StatusGator | Better Stack | |
|---|---|---|
| Vendor Status Aggregation | Yes (core strength) | Optional, not default |
| Custom Synthetic Checks | No | Yes, very granular |
| On-Call Escalation | Basic team filters | Advanced, timezone aware |
| Status Page/Comms | Internal dashboards | External, branded status pages |
| Free Tier | No | Yes |
| API/SIEM Integrations | Standard webhooks | Rich, RESTful APIs |
| Total Cost of Ownership | Low, static workloads | Flexible, effort scales with complexity |
| Best Suited For | Vendor aggregation/compliance | Hands-on, customizable monitoring |
The decision comes down to business drivers: Is the goal to consolidate hundreds of third-party SaaS status feeds? StatusGator wins for simplicity and onboarding velocity. Are you running mission-critical apps, APIs, or want true business-aligned synthetic monitoring and advanced escalation? Better Stack leads in technical depth and operational maturity. For most, a hybrid stack—leveraging each platform’s core strengths—is the standard of care for reliable business outage detection and rapid incident response.